
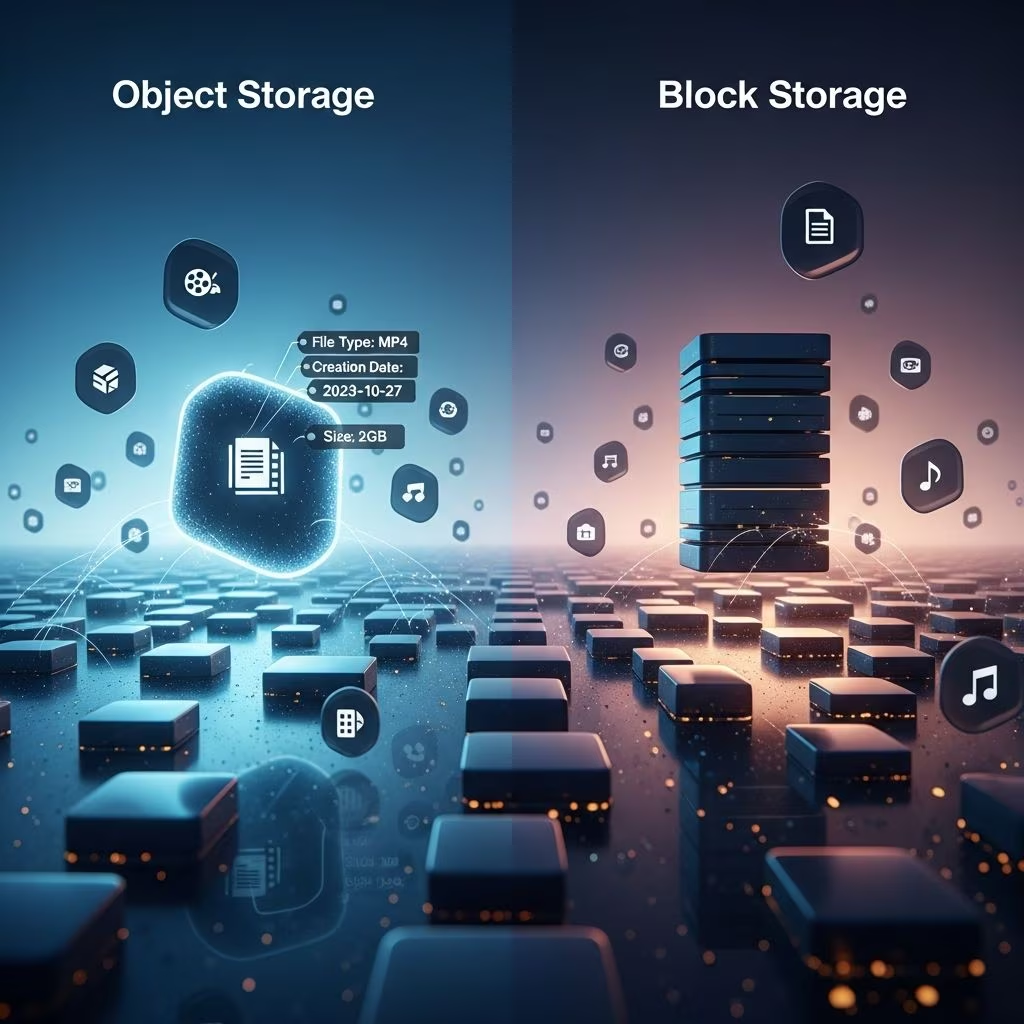
Modern cloud environments demand versatile storage solutions capable of handling diverse workloads efficiently. Among the primary options available, object storage and block storage stand out as fundamental architectures powering everything from massive data lakes to high-performance databases. While both serve critical roles in data management, they differ significantly in structure, performance characteristics, scalability potential, and cost structures.
This comprehensive guide examines these differences in detail, helping IT professionals, developers, and business leaders select the optimal storage type for specific use cases. We’ll explore technical foundations, practical applications, comparative analysis through data tables, and strategic decision-making frameworks grounded in authoritative cloud provider documentation.
Fundamental Architecture Differences
At their core, object storage and block storage organize data using fundamentally different approaches that determine their suitability for various workloads.
Block Storage: Low-Level Data Blocks
Block storage divides files into fixed-size chunks called blocks, typically ranging from 512 bytes to 4KB. Each block receives a unique address, allowing the operating system to access data at the most granular level. This architecture mimics traditional hard disk drives, presenting storage volumes as raw, unformatted space that host file systems (like ext4, NTFS, or XFS) manage directly.
The server treats block storage devices as local disks connected through protocols like iSCSI, Fibre Channel, or NVMe-oF. This direct access enables operating systems to read, write, and modify specific blocks without retrieving entire files, delivering operating system-native performance.
Object Storage: Self-Contained Data Units
Object storage treats each piece of data as a discrete object containing the data itself, descriptive metadata, and a globally unique identifier. Objects reside in flat namespaces within scalable containers (often called buckets), eliminating traditional folder hierarchies.
Unlike block storage, object storage doesn’t rely on host file systems. Applications access objects through RESTful HTTP/S APIs using simple PUT, GET, DELETE, and HEAD operations. This web-native approach enables global distribution and internet-scale access patterns.
Performance Characteristics Comparison
Performance represents one of the most critical differentiators between these storage types, directly impacting application responsiveness and user experience.
| Performance Metric | Block Storage | Object Storage |
|---|---|---|
| Latency | Sub-millisecond (direct I/O) | 10-100ms (HTTP overhead) |
| IOPS | 100K+ (SSD-based) | Thousands (throughput-optimized) |
| Throughput | High for random access | Extreme for sequential reads |
| Concurrency | Single instance focus | Millions simultaneous |
Block storage excels in transactional workloads requiring low-latency random access, such as relational databases (MySQL, PostgreSQL), virtual machine boot volumes, and caching layers. Google Cloud documentation highlights block storage’s multiple data paths and minimal metadata overhead enabling efficient retrieval for performance-critical applications.1
Object storage prioritizes massive throughput for sequential access patterns. While individual object operations incur HTTP latency, parallel requests across distributed object stores deliver aggregate performance surpassing traditional systems for analytics workloads and content delivery.
Scalability and Capacity Planning
Scalability requirements dramatically influence storage architecture selection, particularly for growing enterprises.
- Block Storage Scale Limits: Vertically scales by adding capacity to existing volumes (up to provider limits, typically 64TB per volume). Horizontal scaling requires complex multi-volume RAID configurations or distributed filesystems.
- Object Storage Infinite Scale: Horizontally scales across unlimited nodes and geographic regions. Single buckets handle exabytes without performance degradation or management complexity.
IBM emphasizes object storage’s consumption-based model eliminates capacity planning challenges. Organizations pay only for stored objects, avoiding overprovisioning common with block storage’s fixed volume allocations.2
Cost Structure Analysis
Cost considerations reveal another major differentiator between storage architectures.
| Cost Factor | Block Storage | Object Storage |
|---|---|---|
| Storage Pricing | $0.10-$0.17/GB/month | $0.02-$0.05/GB/month |
| Provisioned Capacity | Required (pay for allocated) | Consumption-based |
| Performance Premium | High (SSD provisioning) | Included in base rate |
| API/Egress Fees | Minimal | Potentially significant |
Oracle documentation confirms block storage’s efficiency for structured data stems from single-file block organization reducing filesystem overhead, though higher costs reflect performance premium.3 Object storage’s pay-as-you-store model proves 70-80% cheaper for archival and infrequently accessed data.
Metadata and Data Management Capabilities
Metadata handling represents object storage’s most compelling advantage over block-based systems.
- Object Storage: Unlimited custom metadata (key-value pairs) per object enables rich content classification, policy enforcement, lifecycle management, and searchability. Metadata travels with objects, persisting through replication and versioning.
- Block Storage: Limited to filesystem metadata (timestamps, permissions, sizes). Advanced metadata requires separate indexing layers adding complexity and cost.
StoneFly analysis demonstrates object storage’s metadata enables content-based policies like automatic tiering, compliance retention, and analytics tagging impossible with block storage’s rigid structure.4
Primary Use Cases and Workload Patterns
Block Storage Workloads
- Database primary storage (OLTP/OLAP)
- Virtual machine and container persistent volumes
- High-performance computing temporary storage
- Application servers requiring low-latency I/O
- Boot volumes and operating system images
Object Storage Workloads
- Backup and disaster recovery archives
- Media repositories (images, video, audio)
- Big data lakes and analytics platforms
- Static website hosting and CDN origin
- Log aggregation and monitoring data
Access Protocols and Integration
Protocol support determines application compatibility and deployment flexibility.
| Protocol | Block Storage | Object Storage |
|---|---|---|
| Primary Access | iSCSI, FC, NVMe-oF | S3, Swift, HTTP/REST |
| OS Native | Full filesystem access | API-based only |
| Cloud Native | Moderate integration | Native compatibility |
| Global Access | VPN/Direct Connect | Internet-accessible |
Red Hat documentation notes object storage’s HTTP-based access enables seamless integration with cloud-native applications, serverless functions, and global content delivery networks.5
Strategic Selection Framework
Choosing between object and block storage requires balancing multiple factors:
- Access Patterns: Random/low-latency → Block; Sequential/bulk → Object
- Data Volume: Terabytes+ → Object; Gigabytes → Block
- Concurrency: Millions users → Object; Single instance → Block
- Cost Sensitivity: Archival/infrequent → Object; Performance-critical → Block
- Management Overhead: Hands-off → Object; Full control → Block
Hybrid Architecture Strategies
Modern enterprises increasingly adopt hybrid approaches leveraging both storage types optimally:
- Active Tier (Block): Real-time databases, application servers
- Cold Tier (Object): Historical data, compliance archives
- Cache Layer: Block for hot data, Object for durable persistence
- Analytics Pipeline: Block for transactional source, Object for data lake
Google Cloud recommends lifecycle policies automatically transitioning data between storage classes based on access patterns and business requirements.1
Future Trends and Considerations
Emerging technologies continue evolving storage capabilities:
- NVMe-oF: Extends block storage performance across networks
- S3 Express One Zone: Ultra-low latency object storage
- Disaggregated Storage: Shared persistent memory pools
- AI/ML Workloads: Object storage optimized for training data pipelines
Frequently Asked Questions
Can I use object storage like a filesystem?
While object storage APIs differ from filesystems, tools like s3fs and goofys provide filesystem-like interfaces with performance tradeoffs. For production workloads, native API access delivers optimal performance.
Is block storage always faster than object storage?
Block storage offers lower latency for random I/O, but object storage can deliver higher aggregate throughput for parallel sequential access patterns common in analytics and media serving.
How do I migrate data between storage types?
Cloud providers offer managed replication services and data transfer tools. Plan migrations during maintenance windows, validate data integrity, and test application compatibility with new storage APIs.
What about file storage as a third option?
File storage (NAS/SMB/NFS) combines hierarchical organization with network access, suitable for shared user drives and legacy applications but limited in cloud-native scalability compared to object storage.
References
- How Object vs Block vs File Storage differ — Google Cloud. 2024-01-15. https://cloud.google.com/discover/object-vs-block-vs-file-storage
- Object vs. File vs. Block Storage: What’s the Difference? — IBM. 2024-03-22. https://www.ibm.com/think/topics/object-vs-file-vs-block-storage
- Object versus Block and File Storage Explained — Oracle Cloud. 2024-02-10. https://www.oracle.com/cloud/storage/block-volumes/what-is-block-storage/vs-object-storage/
- File Storage Vs Block Storage Vs Object Storage: Key Differences — StoneFly. 2023-11-08. https://stonefly.com/blog/file-storage-vs-block-storage-vs-object-storage-comparison/
- File storage, block storage, or object storage? — Red Hat. 2024-04-05. https://www.redhat.com/en/topics/data-storage/file-block-object-storage