
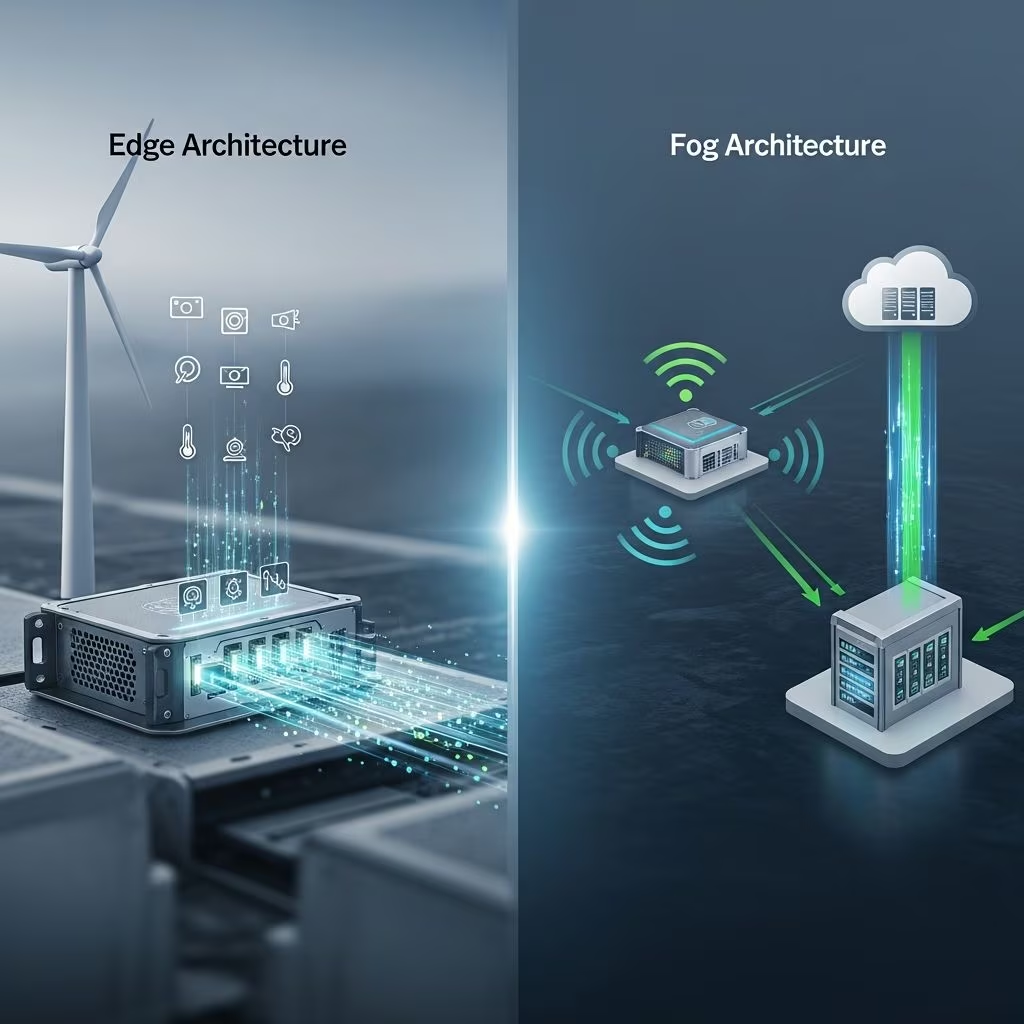
The modern computing landscape has fundamentally shifted from purely centralized cloud models to a more nuanced, geographically distributed approach. Organizations increasingly deploy computing resources at multiple tiers of their network infrastructure, creating a tiered processing model that addresses latency, bandwidth, and real-time responsiveness challenges. Two critical architectural patterns have emerged within this distributed computing paradigm: edge computing and fog computing. While these terms are sometimes used interchangeably, they represent distinct computational strategies with different placement, scope, and operational characteristics.
The Computational Continuum: From Device to Cloud
Modern enterprises operate across a computational spectrum that spans from localized device-level processing all the way to centralized cloud data centers. Understanding this continuum helps clarify where edge and fog computing fit within the broader infrastructure ecosystem. At one end, centralized cloud platforms offer massive computational resources and storage capacity but introduce latency concerns due to physical distance and network transmission delays. At the opposite end, processing data directly on sensors and IoT devices provides instantaneous analysis but requires significant computational resources to be embedded in potentially resource-constrained hardware. Edge and fog computing represent intermediate solutions that balance these competing requirements.
The key insight is that not all data processing benefits from centralized cloud computation, nor is all data processing feasible at the device level. The emergence of edge and fog architectures reflects this practical reality. Organizations now make strategic decisions about where specific computational tasks should occur based on latency requirements, data volume, processing complexity, and security considerations.
Edge Computing: Processing at the Source
Edge computing represents the strategy of placing computational intelligence directly at or immediately adjacent to where data originates. This approach dramatically reduces the physical distance data must travel before analysis occurs. In an edge computing deployment, processing happens on the device itself, within a local gateway device, or on specialized edge appliances positioned within immediate proximity to data sources.
The defining characteristic of edge computing is its emphasis on localized autonomy. Edge devices operate with substantial independence, making real-time decisions based on locally available data without requiring constant communication with distant systems. This independence offers several distinct advantages:
- Immediate Response Times: Decision-making occurs in milliseconds rather than seconds, critical for applications where delayed responses create safety or operational risks
- Reduced Bandwidth Consumption: By processing data locally and transmitting only meaningful results, edge computing significantly decreases the volume of traffic flowing through network infrastructure
- Enhanced Data Privacy: Sensitive information remains on local systems rather than being transmitted across networks, addressing regulatory and security requirements
- Operational Resilience: Edge systems continue functioning even when connectivity to central systems is temporarily interrupted
Edge computing finds natural application in scenarios requiring immediate, localized decision-making. Manufacturing facilities deploy edge processing to monitor equipment conditions and trigger alerts instantly. Healthcare providers utilize edge computing for wearable devices and patient monitoring equipment that must respond to critical changes without network delays. Autonomous vehicles rely entirely on edge computing for navigation and obstacle detection, processing sensor data in real-time to ensure passenger safety.
Fog Computing: Aggregation and Intermediate Processing
Fog computing introduces an additional architectural layer positioned between edge devices and centralized cloud infrastructure. Rather than processing occurring only at the device level, fog computing establishes intermediate processing nodes that aggregate, filter, and analyze data from multiple edge sources. These fog nodes might exist at network gateways, local area networks, or specialized aggregation points distributed across an organization’s infrastructure.
The fog computing model addresses a specific challenge that emerges when edge deployments scale across numerous devices and locations. While edge processing excels at localized, immediate analysis, it often lacks the capability to synthesize information across multiple sources or perform sophisticated analysis on aggregated datasets. Fog computing bridges this gap by establishing a layer of more capable computational resources that can analyze patterns and trends across distributed edge devices.
Fog nodes perform several critical functions within this architecture:
- Data Filtering and Prioritization: Fog nodes receive data streams from multiple edge devices and determine which information warrants transmission to central systems for long-term storage and advanced analytics
- Intermediate Analysis: More sophisticated processing occurs at the fog layer, identifying patterns or correlations that emerge only when considering data from multiple sources
- Caching and Local Storage: Fog nodes maintain temporary storage of relevant data, reducing pressure on centralized storage systems and ensuring faster data access for frequently requested information
- Protocol Translation and Data Normalization: As edge devices from different manufacturers send data in varying formats, fog nodes standardize this information for consistent downstream processing
Architectural Positioning and Deployment Models
The most fundamental distinction between edge and fog computing relates to their physical positioning within network infrastructure and their role within the broader processing pipeline. Edge computing pushes computational capabilities as close as possible to data sources, often embedding intelligence directly within IoT devices, sensors, or specialized hardware deployed in the field. This approach prioritizes proximity and autonomy.
Fog computing, by contrast, establishes a distributed middle layer that operates at a higher level within network architecture. Fog nodes typically operate at Local Area Network (LAN) boundaries, network gateways, or Points of Presence (PoPs) within carrier networks. This positioning allows fog infrastructure to collect data from numerous edge devices spread across a geographic area and perform coordinated analysis.
The architectural relationship between these approaches is hierarchical and complementary. Edge computing serves as the initial data collection and processing tier. Data that edge devices determine requires further analysis or that exhibits patterns requiring multi-source correlation flows to fog nodes. Fog nodes then determine what information merits transmission to centralized cloud systems for permanent storage, advanced analytics, or machine learning model training.
Scalability Considerations and Resource Management
Scalability characteristics differ significantly between edge and fog computing models, creating important implications for infrastructure planning and deployment strategy. Edge computing scales primarily through the addition of more individual devices. However, each edge device remains fundamentally limited in computational capacity and storage availability. As organizations deploy thousands or millions of edge devices, the cumulative processing power grows but coordination becomes increasingly complex.
Fog computing introduces different scalability dynamics. Because fog nodes operate at a higher architectural layer, they can coordinate and analyze data from numerous edge devices. Adding additional fog nodes increases overall system capacity while maintaining coherent data processing across the entire infrastructure. Fog architectures can service vastly larger numbers of edge devices through a comparatively modest number of fog nodes. This aggregation approach enables more efficient resource utilization at scale.
However, this scalability advantage comes with increased architectural complexity. Fog computing requires sophisticated orchestration to direct data flows appropriately, manage redundancy across distributed fog nodes, and maintain consistency across multiple processing tiers. Organizations must invest in monitoring and management systems that provide visibility across this multi-layered infrastructure.
Latency, Throughput, and Processing Implications
The positioning differences between edge and fog computing create distinct performance characteristics that influence technology selection for specific applications. Edge computing delivers the absolute lowest latency since processing occurs immediately at data sources. Applications requiring sub-millisecond response times depend on edge computing capabilities. Manufacturing defect detection, autonomous vehicle obstacle recognition, and real-time industrial process control all represent scenarios where edge computing’s latency characteristics prove essential.
Fog computing introduces slightly higher latency since data must traverse from edge devices to fog nodes before analysis occurs. However, fog computing maintains substantially lower latency than centralized cloud processing since fog nodes operate within the organization’s local network infrastructure rather than at distant data centers. For applications requiring response times measured in tens of milliseconds, fog computing often provides acceptable performance while enabling the more sophisticated analysis that centralized systems cannot support.
Throughput handling represents another dimension where these architectures differ. Edge devices typically process relatively limited data volumes since they operate on individual devices or local sensors. Fog nodes, positioned to aggregate data from many edge devices, can handle significantly higher throughput. This throughput advantage makes fog computing suitable for applications involving large-scale IoT deployments or complex analytics requiring correlation across multiple data streams.
Data Management and Storage Architecture
Data handling strategies diverge considerably between edge and fog computing models, with implications for data residency, privacy compliance, and operational efficiency. In edge computing implementations, data remains predominantly on individual devices or in extremely local storage. Processed results may be transmitted elsewhere, but the original raw data stays where it was generated. This approach minimizes data transmission requirements and naturally supports data residency regulations requiring information to remain within specific geographic boundaries.
Fog computing introduces intermediate storage and data curation. Fog nodes maintain temporary storage of data received from edge devices, enabling analysis across multiple data streams. Fog nodes make intelligent decisions about what data merits retention for longer-term analysis versus what can be discarded as redundant or unimportant. This curation significantly reduces the volume of data transmitted to centralized cloud systems, decreasing bandwidth requirements and long-term storage costs.
The different data handling approaches create distinct security and privacy profiles. Edge computing’s local-processing model naturally contains sensitive data within device boundaries, addressing regulatory requirements in healthcare, finance, and government sectors. Fog computing’s intermediate aggregation provides additional opportunities for data anonymization, aggregation, and filtering before information travels to external systems, balancing the need for centralized analytics with privacy requirements.
Use Case Differentiation and Technology Selection
Distinguishing between edge and fog computing based on use case characteristics helps organizations select appropriate technologies. Edge computing proves optimal for applications demanding immediate, localized response without requiring coordination across multiple systems. Wearable health monitors, smart home devices responding to local conditions, and manufacturing equipment detecting immediate anomalies all benefit from edge computing’s autonomous decision-making capabilities.
Fog computing excels in scenarios requiring analysis across distributed sources but not demanding absolute minimal latency. Smart city applications aggregating traffic data from numerous sensors to optimize traffic flow patterns represent ideal fog computing use cases. Predictive maintenance systems analyzing sensor data from equipment across a facility to identify emerging failures benefit from fog computing’s intermediate aggregation capabilities. Large-scale IoT implementations involving thousands of devices naturally leverage fog computing for coordinated analysis.
Organizations frequently deploy both technologies in hybrid architectures that leverage the strengths of each approach. Edge devices handle immediate, localized processing and response. Fog nodes aggregate and analyze patterns emerging across multiple edge devices. Centralized cloud systems perform advanced analytics, machine learning model development, and long-term historical analysis. This tiered approach balances responsiveness, analytical capability, and cost efficiency.
Architectural Complexity and Operational Considerations
The operational burden associated with each technology approach differs significantly. Edge computing implementations may involve numerous individual devices requiring individual monitoring and management, but the processing logic remains relatively straightforward. Each device operates independently with minimal coordination requirements.
Fog computing introduces substantially greater architectural complexity. Organizations must establish redundancy strategies across fog nodes, implement data consistency mechanisms when multiple fog nodes process related information, and develop sophisticated monitoring to track data flows across the distributed infrastructure. Each communication link in a fog architecture represents a potential point of failure, requiring careful network design and monitoring.
Maintenance and troubleshooting become more challenging in fog environments due to the distributed nature of processing. Identifying whether processing delays stem from edge device issues, fog node bottlenecks, or network connectivity problems requires comprehensive visibility across all layers. Organizations deploying fog computing must invest in monitoring and observability tools that provide end-to-end visibility across the distributed infrastructure.
Economic Considerations and Cost Implications
Cost structures differ between these architectural approaches in ways that influence selection decisions. Edge computing requires embedding processing capabilities in numerous individual devices, increasing per-device hardware costs. However, edge computing minimizes bandwidth consumption through local processing, reducing long-term operational costs associated with data transmission. The total cost of ownership depends on device count, bandwidth pricing, and cloud storage requirements.
Fog computing requires fewer specialized appliances positioned strategically throughout infrastructure, potentially reducing total hardware investment. However, fog computing consumes more bandwidth than pure edge approaches since aggregated data flows between edge and fog layers. Organizations must carefully analyze their specific requirements to determine whether edge computing’s higher hardware costs but lower bandwidth consumption, or fog computing’s lower hardware costs but higher bandwidth consumption, produces more favorable total cost of ownership.
Future Considerations and Architectural Evolution
As organizations continue expanding IoT deployments and exploring real-time analytics opportunities, understanding edge and fog computing becomes increasingly critical. Neither technology represents a complete replacement for cloud computing; instead, all three approaches will coexist in increasingly sophisticated hybrid architectures. Edge computing will handle immediate, localized processing. Fog computing will manage intermediate aggregation and analysis across distributed edge devices. Cloud computing will continue supporting advanced analytics, machine learning, and long-term historical analysis.
The fundamental principle guiding future evolution remains consistent: processing should occur at the most appropriate layer within the computational hierarchy, balancing responsiveness requirements, analytical needs, cost efficiency, and security constraints. Organizations that develop expertise in designing and operating multi-layered computing architectures will successfully address the challenges of increasingly distributed, data-intensive operations.
References
- Edge vs. Fog vs. Cloud: The Modern IT Solution Explained — Scale Computing. 2024. https://www.scalecomputing.com/resources/edge-computing-vs-fog-computing-vs-cloud-computing
- Understanding Fog Computing vs Edge Computing — OnLogic. 2024. https://www.onlogic.com/blog/fog-computing-vs-edge-computing/
- Fog vs Edge Computing: What’s the difference? — Opto 22. 2024. https://info.opto22.com/fog-vs-edge-computing
- The differences between cloud, fog and edge computing — TechTarget. 2024. https://www.techtarget.com/searchnetworking/answer/Fog-computing-vs-edge-computing-Whats-the-difference
- Difference Between Edge Computing and Fog Computing — GeeksforGeeks. 2024. https://www.geeksforgeeks.org/difference-between-edge-computing-and-fog-computing/
- Edge Computing VS Fog Computing: A Comprehensive Guide — Xailient. 2024. https://xailient.com/blog/edge-computing-vs-fog-computing-a-comprehensive-guide/
- Fog vs. Edge Computing: Key Differences Explained — Penguin Solutions. 2024. https://www.penguinsolutions.com/en-us/resources/blog/fog-computing-similarities-and-differences-edge-computing